
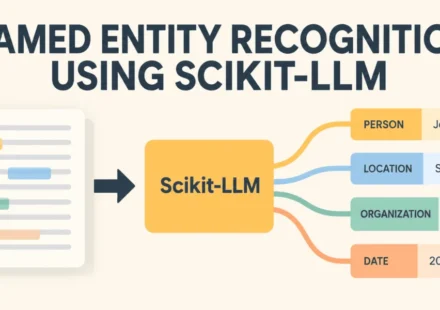
Leveraging Large Language Models for Efficient Named Entity Recognition with Scikit-LLM

Structured data extraction from unstructured text is a cornerstone of modern data analysis, powering everything from predictive machine learning models to sophisticated business intelligence tools. Among the most critical tasks in this domain is Named…
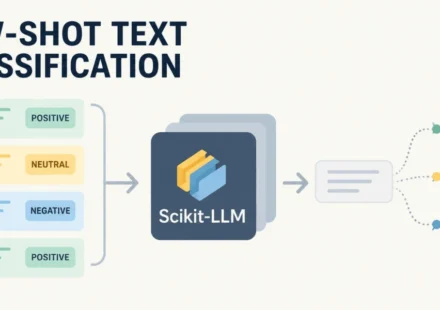
Bridging the Gap: Scikit-LLM Empowers Few-Shot Text Classification with Familiar Scikit-learn Interface

The landscape of text classification, once a domain demanding extensive labeled datasets and intricate feature engineering, is undergoing a profound transformation with the advent of Large Language Models (LLMs). Traditionally, building a robust text…
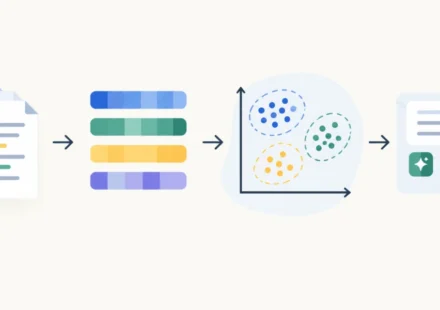
Building a Lightweight RAG Pipeline with Scikit-Learn and Open-Source LLMs

The rapid evolution of generative artificial intelligence has led to the widespread adoption of Retrieval-Augmented Generation (RAG), a technique that bridges the gap between static large language models (LLMs) and dynamic, private, or specialized…
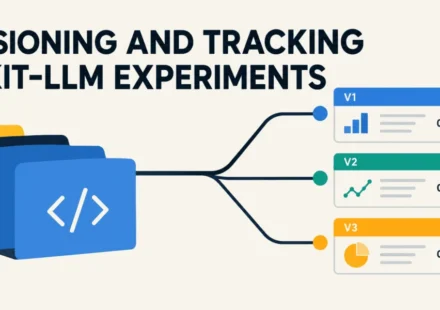
Mastering the Lifecycle of Scikit-LLM Pipelines with MLflow for Enhanced Model Tracking and Versioning

The rapid evolution of generative artificial intelligence has necessitated a shift in how developers approach machine learning workflows, moving away from ad-hoc prompting toward structured, reproducible, and version-controlled pipelines. As enterprises…
