
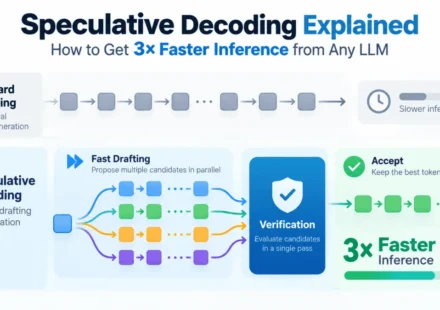
Speculative Decoding: The Architectural Breakthrough Accelerating Large Language Model Inference

Comments Off on Speculative Decoding: The Architectural Breakthrough Accelerating Large Language Model Inference
The rapid proliferation of Large Language Models (LLMs) has revolutionized the tech landscape, yet a persistent technical bottleneck remains: the speed of text generation. As models like GPT-4, Claude, and Llama grow in complexity, the latency inherent…
