OpenAlex Emerges as Critical Open Infrastructure, Challenging Proprietary Scholarly Data Systems and Calling for Community-Wide Curation Efforts

The scholarly publishing landscape is experiencing a significant shift, with a growing number of research institutions and systems increasingly relying on open infrastructure to map scholarly output. This transition marks a pivotal moment, challenging the long-standing dominance of proprietary databases and ushering in an era where the accuracy and accessibility of underlying research data are paramount. At the forefront of this movement is OpenAlex, an ambitious open-source project designed to be a comprehensive and freely accessible index of global scholarship.
A Paradigm Shift: Sorbonne University Leads the Way
A notable testament to this evolving trend occurred in 2024 when Sorbonne University in France, a globally recognized institution, made headlines by announcing its decision to unsubscribe from the proprietary Web of Science data and instead embrace OpenAlex’s open infrastructure. This strategic move by a major university signals a growing recognition of the value and potential of open data in academic research. For the Sorbonne, OpenAlex now serves as an essential assistant layer for its library operations, providing an alternative that aligns with the principles of open science and data autonomy.
The implications of such a shift extend far beyond individual library systems. OpenAlex is not merely a replacement for traditional bibliographic databases; it functions as a foundational data layer for a diverse array of tools and applications across the scholarly ecosystem. Its data underpins funder reporting dashboards, informs global rankings such as the CWTS Leiden Ranking, and powers new AI-driven research assistants. The pervasive nature of OpenAlex means that while most end-users may not directly interact with it, its underlying data directly influences the tools they use daily. This ubiquity underscores a critical point: any error in this foundational "map of who published what" does not remain isolated. Instead, it propagates silently and systemically into every tool built upon it, including those publishers and researchers utilize to track their own impact and assess scholarly contributions.
The Genesis of OpenAlex: A Legacy of Openness
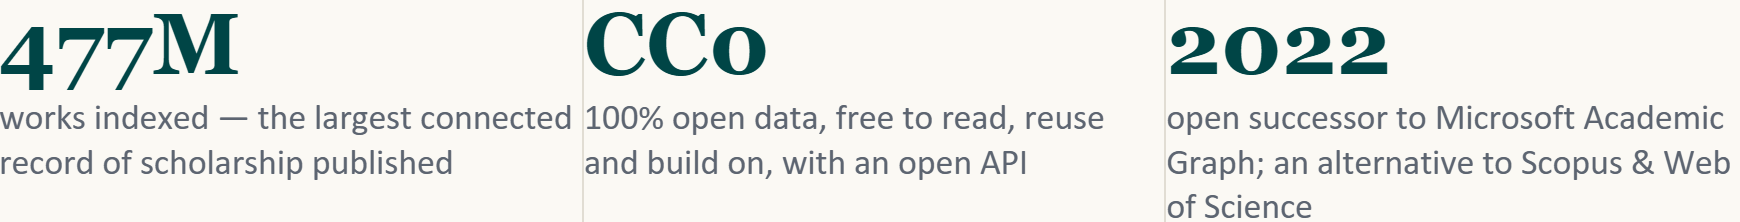
OpenAlex, launched in 2022, was conceived as the open successor to Microsoft Academic Graph (MAG), an initiative that provided a vast, interconnected dataset of scientific publications. Named in homage to the ancient Library of Alexandria, a symbol of universal knowledge, OpenAlex is maintained as a public good by the non-profit organization OurResearch. Its mission is to democratize access to scholarly information by indexing hundreds of millions of works, authors, institutions, sources, and funders, along with the intricate web of connections between them. Crucially, all of this data is made available under a fully open license (CC0), allowing anyone to freely read, reuse, or build upon it within specified usage limits.
The scale and accessibility of OpenAlex are genuinely impressive. In just a few years, it has rapidly become one of the largest connected records of scholarship in existence, offering an alternative to established, subscription-based services like Scopus and the Web of Science. This open approach stands in stark contrast to the closed, proprietary models that have dominated scholarly indexing for decades.
The Historical Context: Proprietary Dominance and the Rise of Open Science
For much of the late 20th and early 21st centuries, the landscape of scholarly indexing was largely defined by proprietary databases. Clarivate Analytics’ Web of Science, with its roots tracing back to the 1960s with Eugene Garfield’s pioneering work on citation indexing, and Elsevier’s Scopus, launched in 2004, became indispensable tools for researchers, institutions, and funders. These platforms offered comprehensive coverage, sophisticated citation metrics, and robust search functionalities, enabling precise bibliometric analysis and research evaluation. Their value was undeniable, facilitating discovery and assessment in an increasingly vast and complex research environment.
However, the proprietary nature of these systems came with significant drawbacks. High subscription costs placed a heavy financial burden on academic institutions, particularly those in developing regions, exacerbating inequalities in access to critical research data. Concerns also mounted regarding vendor lock-in, limited transparency in data curation, and the potential for commercial interests to influence research evaluation metrics.
Parallel to the growth of these proprietary systems, the "open science" movement gained momentum. Driven by principles of transparency, accessibility, and collaboration, this movement advocated for open access to publications, open data, and open methodologies. Initiatives like the FAIR (Findable, Accessible, Interoperable, Reusable) data principles emerged, emphasizing the ethical and practical imperative to make research outputs openly available. Funders and governments increasingly mandated public access to research funded by taxpayer money, further fueling the demand for open infrastructure. OpenAlex, therefore, did not emerge in a vacuum but as a direct response to this broader cultural and systemic shift, offering a robust, community-driven solution that aligns with the evolving values of the global research community.
The Silent Challenge: Data Disambiguation at Scale
While OpenAlex’s scale and openness are monumental achievements, they also bring forth its most significant challenge: data disambiguation. Accurately matching tens of millions of papers to the correct authors, institutions, and other entities is an inherently complex problem in bibliometrics. Even highly sophisticated algorithms, when applied across hundreds of millions of works, are bound to produce a meaningful number of errors.
The failure modes of such systems are well-understood and multifaceted. Common names present a pervasive ambiguity that escalates with scale; imagine distinguishing between dozens of "J. Smith" or "Li Wei" in a global database. Researchers often publish under inconsistent variants of their own names throughout their careers, whether due to maiden names, varying use of middle initials, or simple typographical errors. Institutional affiliations change as academics move between universities, and two researchers with similar names at the same institution can become nearly indistinguishable when relying solely on citation data.
The consequences of these disambiguation failures manifest in two primary ways:
- Split Identities: A single author’s body of work is erroneously fragmented across multiple profiles, leading to an inaccurate representation of their complete scholarly output.
- Merged Identities: The work of two or more distinct academics is incorrectly conflated into a single profile, misattributing publications and distorting individual research records.
While some researchers have linked their ORCID (Open Researcher and Contributor ID) to their OpenAlex profiles, providing a strong signal for the algorithm, ORCID adoption is not universal, nor is its consistent use. This means that ORCID, while incredibly valuable, only partially addresses the broader disambiguation problem. The result of these unconfirmed data points is not intentionally wrong information, but rather data that remains unverified until a human intervention. This issue extends beyond simple discoverability; critical research integrity tools designed to detect issues like paper mills and citation manipulation rely heavily on accurate authorship data. When records are thin or misattributed, these tools lose precision at precisely the moments when accuracy is most crucial for maintaining the integrity of the scholarly record.
The Human Element: Community Curation as the Solution
The most effective solution to the pervasive problem of data disambiguation is overwhelmingly human-driven. An author claiming their own profile, merging name variants, and linking their ORCID provides the definitive resolution that algorithms alone cannot achieve. This act of curation is not merely an administrative chore; it is a fundamental contribution to the reliability of the shared scholarly infrastructure.
Publishers are uniquely positioned to facilitate this crucial human intervention. They are in direct, trusted contact with authors at critical junctures of their scholarly journey: upon acceptance of a manuscript and at the point of publication. These moments are when authors are most engaged with their scholarly identity and most invested in ensuring their work is accurately represented. A brief, well-timed prompt from a publisher, embedded within an acceptance or publication email, can be far more effective than a generic, unsolicited invitation to update a profile.
Furthermore, publishers possess an additional, often overlooked, source of unification: manuscript submission systems. An academic with a common name who has published without consistently specifying an ORCID might still have used a single, consistent account across various submission platforms. This internal publisher data can serve as valuable evidence, confirming that a body of work belongs to a single academic author, thereby aiding in the disambiguation process.
Publishers’ Crucial Role: From Gatekeepers to Enablers
The question then arises: why should publishers invest their limited resources in encouraging authors to claim their OpenAlex profiles, particularly when researchers already navigate a multitude of platforms like Google Scholar, ResearchGate, ORCID, institutional repositories (e.g., Pure), and personal profile sites (e.g., Loop)?
For publishers who directly integrate OpenAlex data into their operations, the answer is straightforward: improved data quality directly enhances their internal analyses and services. However, the benefits extend far beyond direct data usage. Many vendors and service providers that publishers rely on – for everything from reviewer suggestions and citation checks to plagiarism detection and conflict of interest declarations – increasingly draw from OpenAlex as a primary source. Enhancements to OpenAlex’s underlying data directly translate to higher quality, more precise services for publishers.
Moreover, the accuracy of author data in OpenAlex directly impacts how a journal’s own output is attributed, discovered, and counted in external metrics, rankings, and funder reports. Every author who claims and curates their profile contributes to a more reliable foundation for these critical assessments. The cost of prompting authors is minimal – a simple sentence in an email requires no new systems, budget allocations, or additional staff time. The benefits, however, are substantial and ripple across the entire ecosystem. Because OpenAlex is open, a single correction made by an author improves every platform and tool that builds on that data. This collective effort makes the shared map of scholarship more trustworthy for the author, for the publisher whose metadata depends on it, and for every reader and tool downstream.
The Broader Implications: Reshaping the Scholarly Ecosystem
The widespread adoption and accurate curation of OpenAlex have profound implications for various stakeholders within the scholarly ecosystem:
- For Institutions: By reducing reliance on costly proprietary databases, institutions can achieve significant cost savings and redirect funds towards other research and educational priorities. Furthermore, it empowers them with greater autonomy over their data, fostering internal reporting and analysis capabilities that are aligned with open science principles.
- For Funders: More accurate and comprehensive data on research output and impact enables funders to make better-informed decisions regarding grant allocation, assess the societal return on investment more effectively, and track the progress of funded research with greater precision.
- For Researchers: Accurate OpenAlex profiles enhance discoverability, ensuring that their work is correctly attributed and easily found by peers. It supports more precise evaluation of their contributions, bolstering their professional reputation and providing a clearer picture of their scholarly impact. It also contributes to more reliable research integrity tools, protecting the credibility of their work and the wider scientific enterprise.
- For AI and Bibliometric Tools: As AI-driven research assistants and advanced bibliometric tools become more prevalent, the quality of their underlying data is paramount. OpenAlex provides a rich, openly accessible dataset that can fuel innovation in these areas, leading to more sophisticated analyses, better trend identification, and more intelligent scholarly discovery tools.
- For the Scholarly Community at Large: OpenAlex fosters a more equitable and transparent scholarly environment. By making research data freely available and accurately attributed, it reduces barriers to knowledge access, promotes collaboration, and accelerates the pace of scientific progress globally.
The commitment of OpenAlex to build and maintain this ledger of academic content in the open, combined with its ambition to set the record straight, warrants the time and support of academic researchers and publishers alike. It represents a powerful combination of open source principles and a dedication to data quality, returning the value of scholarly infrastructure directly to the academic community it serves.
A Collective Responsibility for Open Knowledge
In essence, OpenAlex embodies the principle that open knowledge is not passively owned but actively maintained by all who benefit from it. Publishers, with their unique position at the nexus of authors and the scholarly record, have a critical role to play in this collective endeavor. They have historically borne the responsibility for the quality and integrity of the scholarly record within their own journals. Helping authors claim and maintain their OpenAlex profiles extends this responsibility to the broader, shared infrastructure upon which so much of academia now relies. Few organizations are as well-placed or possess the necessary direct lines of communication to effectively champion this crucial step. By embracing this role, publishers can not only enhance their own operations but also contribute significantly to a more accurate, transparent, and equitable global scholarly landscape.