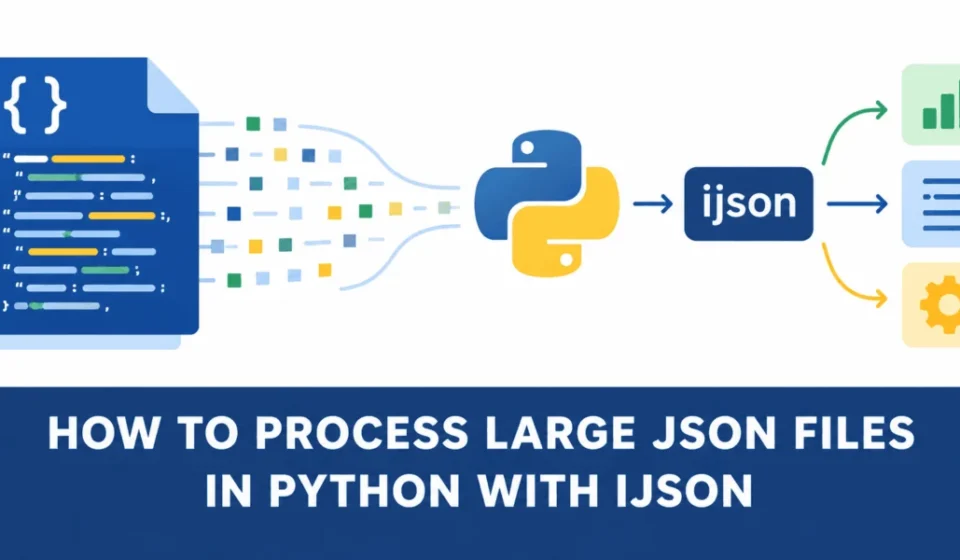

JSON (JavaScript Object Notation) has become a cornerstone of data exchange and storage within Python applications. While the built-in json module efficiently handles smaller files, its limitations become apparent when faced with datasets of significant size. The standard json.load() function parses the entire JSON document into memory, transforming it into Python objects such as dictionaries, lists, and numerical types. This process can lead to substantial memory consumption, far exceeding the on-disk size of the original file, especially when dealing with hundreds of megabytes or gigabytes of data. For such demanding workloads, an iterative JSON parser like ijson offers a more scalable and memory-efficient solution by enabling incremental data processing. This article explores the challenges of processing large JSON files with Python’s standard library and demonstrates how ijson provides a robust alternative.
The Memory Challenge of Standard JSON Parsing
The conventional approach to loading JSON data in Python involves the json module. For a file named data.json, the process is typically as follows:
import json

with open("data.json") as f:
    data = json.load(f)
This seemingly straightforward code snippet, while perfectly adequate for small to medium-sized files, presents a significant bottleneck when encountering large datasets. The json.load() function operates by reading the entire content of the file, parsing it thoroughly, and then constructing the corresponding Python data structures in RAM. Consequently, a JSON file that occupies, for instance, 200 MB on disk could demand over 800 MB of memory once loaded, due to the overhead of representing JSON elements as Python objects. This memory bloat can quickly lead to performance degradation, MemoryError exceptions, and system instability, particularly in resource-constrained environments or when processing multiple large files concurrently.
Case Study: San Francisco Land Parcel Data
To illustrate the practical implications of this memory challenge, we will utilize a real-world dataset: the San Francisco City Lots dataset. This dataset, formatted as a GeoJSON FeatureCollection, contains detailed information about land parcels across the city.
Step 1: Acquiring and Inspecting the Dataset
The San Francisco City Lots dataset can be downloaded using the following command, assuming a Unix-like environment:
curl -L
https://raw.githubusercontent.com/zemirco/sf-city-lots-json/master/citylots.json
-o citylots.json
After downloading, we can check its size:
ls -lh citylots.jsonThe file size is approximately 181 MB. This size is substantial enough to effectively demonstrate the differences in memory usage between standard and iterative parsing methods.
The dataset adheres to the GeoJSON FeatureCollection standard, which typically includes a type field (e.g., "FeatureCollection") and a features array. Each element within the features array represents a single land parcel and contains a properties object and a geometry object.
A quick inspection using Python’s json module reveals the structure:
import json

with open("citylots.json", "r") as f:
    data = json.load(f)

print(data.keys())
print(data["features"][0])
The output confirms the type and features keys, and shows an example of a feature with its properties (including MAPBLKLOT, BLKLOT, BLOCK_NUM, LOT_NUM, STREET, etc.) and geometry (defining the polygon coordinates of the parcel). For analytical purposes, often only a subset of this data, such as the STREET and BLKLOT from the properties, is required. However, with json.load(), the entire geometry data, including extensive lists of coordinates, is loaded into memory, contributing significantly to the memory footprint.
Step 2: The Pitfalls of json.load() in Practice
Let’s simulate a common analytical task: counting parcels located on "MARKET" street and identifying the first five such parcel IDs. A naive implementation using json.load() would look like this:
import json
import time

start = time.perf_counter()

with open("citylots.json", "r") as f:
    data = json.load(f)  # This line is the memory bottleneck

features = data["features"]

market_count = 0
first_five = []

for feature in features:
    properties = feature["properties"]
    if properties.get("STREET") == "MARKET":
        market_count += 1
        if len(first_five) < 5:
            first_five.append(properties.get("BLKLOT"))

elapsed = time.perf_counter() - start

print(f"Total parcels: len(features):,")
print(f"Market Street parcels: market_count:,")
print(f"First five parcel IDs: first_five")
print(f"Time: elapsed:.2f seconds")
The execution of this script yields:
Total parcels: 206,560
Market Street parcels: 808
First five parcel IDs: ['0265003', '0265004', '0265005', '0290012', '0291001']
Time: 4.01 seconds
While the results are correct, the critical issue lies in the data = json.load(f) line. Before the loop even begins to process the first parcel, Python must:
- Read the entire 181 MB file from disk.
- Parse every JSON object, array, string, and number.
- Create corresponding Python dictionaries, lists, strings, and numerical objects.
- Store all these objects in RAM.
- Finally, begin the analytical loop.
This process loads not only the STREET and BLKLOT data we need but also the extensive geometry data for every single parcel, which is unnecessary for this specific analysis.
Step 3: Quantifying Memory Consumption with memory-profiler
To empirically demonstrate the memory overhead, we can employ the memory-profiler library. After installing it (pip install memory-profiler), we can instrument the json.load() approach:
from memory_profiler import profile
import json

@profile
def process_file_standard():
    with open("citylots.json", "r") as f:
        data = json.load(f) # Memory-intensive operation

    features = data["features"]
    market_count = 0

    for feature in features:
        if feature["properties"].get("STREET") == "MARKET":
            market_count += 1

# Execution command: python -m memory_profiler standard_json.py
Running this script with python -m memory_profiler standard_json.py reveals the memory profile:
Line #    Mem usage    Increment  Occurrences   Line Contents
=============================================================
     5     43.4 MiB     43.4 MiB           1   @profile
     6                                         def process_file_standard():
     7
     8    808.9 MiB      0.0 MiB           2       with open("citylots.json", "r") as f:
     9    808.9 MiB    765.5 MiB           1           data = json.load(f)
    10
    11    808.9 MiB      0.0 MiB           1       features = data["features"]
    ...
The data = json.load(f) line clearly shows a jump from approximately 43.4 MiB to 808.9 MiB, a staggering increase of over 765 MiB. This highlights a critical point: the memory footprint of a parsed JSON file can be several times larger than its on-disk size. This is because JSON primitives like strings and numbers are represented by more complex Python objects, and nested structures incur additional overhead. For instance, a simple JSON object like "STREET": "MARKET" translates into a Python dictionary, a string key, and a string value, all occupying distinct memory spaces.
Step 4: Introducing ijson for Efficient Streaming
The ijson library offers a paradigm shift by acting as an iterative JSON parser. Instead of loading the entire document at once, ijson allows you to process the JSON stream piece by piece, yielding individual components as they are encountered. This significantly reduces memory requirements, as only a small portion of the data needs to be held in memory at any given time.
The key function for this purpose is ijson.items(). This function takes a file-like object and a prefix, which specifies the path to the items you want to iterate over. For our GeoJSON FeatureCollection, the structure is root -> features (an array) -> item (each element within the array). Therefore, the prefix "features.item" instructs ijson to yield each individual feature object from the features array.
Here’s how to use ijson.items() to iterate over the features:
import ijson

with open("citylots.json", "rb") as f:  # Open in binary mode for ijson
    for feature in ijson.items(f, "features.item"):
        print(feature)
        break
This code snippet will print the first feature object it encounters without loading the entire features array into memory. The conceptual model changes from "load everything, then process" to a stream: "read a piece, process it, discard it, then move to the next piece." This streaming approach is fundamentally more memory-efficient for large datasets.
Step 5: Replicating Analysis with ijson
Now, let’s apply the ijson streaming approach to perform the same analysis: counting Market Street parcels and identifying the first five.
Create a new Python script, stream_json.py:
import ijson
import time

start = time.perf_counter()

total = 0
market_count = 0
first_five = []

with open("citylots.json", "rb") as f:
    for feature in ijson.items(f, "features.item"):
        total += 1
        properties = feature["properties"]
        if properties.get("STREET") == "MARKET":
            market_count += 1
            if len(first_five) < 5:
                first_five.append(properties.get("BLKLOT"))

elapsed = time.perf_counter() - start

print(f"Total parcels: total:,")
print(f"Market Street parcels: market_count:,")
print(f"First five parcel IDs: first_five")
print(f"Time: elapsed:.2f seconds")
The output of this script is:
Total parcels: 206,560
Market Street parcels: 808
First five parcel IDs: ['0265003', '0265004', '0265005', '0290012', '0291001']
Time: 4.58 seconds
Notice the absence of data = json.load(f) and features = data["features"]. Instead, the for feature in ijson.items(...) loop directly processes each feature as it’s parsed from the stream. At any given moment, the memory usage is primarily for the current feature being processed, the internal buffer of the ijson parser, a few counters, and the small list first_five. The memory footprint remains remarkably stable and does not grow with the total size of the JSON document.
To further quantify this improvement, we re-run the memory profiling with ijson:
from memory_profiler import profile
import ijson

@profile
def process_file_streaming():
    total = 0
    market_count = 0
    first_five = []

    with open("citylots.json", "rb") as f:
        for feature in ijson.items(f, "features.item"):
            total += 1
            if feature["properties"].get("STREET") == "MARKET":
                market_count += 1
                if len(first_five) < 5:
                    first_five.append(feature["properties"].get("BLKLOT"))

# Execution command: python -m memory_profiler stream_json.py
The memory profile shows a stark contrast:
Line #    Mem usage    Increment  Occurrences   Line Contents
=============================================================
     5     43.8 MiB     43.8 MiB           1   @profile
     6                                         def process_file_streaming():
     7
     8     43.8 MiB      0.0 MiB           1       total = 0
     9     43.8 MiB      0.0 MiB           1       market_count = 0
    10     43.8 MiB      0.0 MiB           1       first_five = []
    11
    12     46.1 MiB      0.0 MiB           2       with open("citylots.json", "rb") as f:
    13
    14     46.1 MiB      2.2 MiB      206562           for feature in ijson.items(
    ...
The peak memory usage stabilizes around 46.1 MiB, a dramatic reduction from the 808.9 MiB consumed by the standard json.load() approach.
Comparative Analysis: Memory Efficiency and Performance
| Approach | Input File Size | Peak Memory Usage | Processing Model |
|---|---|---|---|
json.load() |
181 MB | ~808.9 MiB | Load entire document |
ijson.items() |
181 MB | ~46.1 MiB | Stream records |
| Difference | Same file | ~762.8 MiB less memory | Significantly more efficient |
This comparison underscores the primary advantage of ijson: its ability to handle large JSON files without a proportional increase in memory consumption. While json.load() might sometimes offer faster parsing if sufficient RAM is available, ijson provides crucial scalability and stability, preventing memory-related failures. The processing time difference (4.01s vs. 4.58s) is negligible in this context, especially when weighed against the substantial memory savings.
Broader Implications and Best Practices
The challenges presented by large JSON files are not unique to this specific dataset. Any application that frequently processes extensive JSON data, such as log aggregation, IoT data streams, or geospatial data processing, can benefit from iterative parsing techniques.
Key Takeaways for Developers:
- Understand Your Data Needs: Before processing, determine exactly which parts of the JSON document are necessary for your task. If you only need specific fields or individual records, loading the entire file is often inefficient and unnecessary.
- Leverage Iterative Parsers: For large JSON files, libraries like
ijsonare indispensable. They enable a "read-process-discard" workflow, drastically reducing memory overhead. - Consider the Prefix: When using
ijson.items(), carefully define the prefix to target the specific nested structures you need to iterate over. This allows for fine-grained control over the parsing process. - File Mode:
ijsontypically works best with files opened in binary mode ("rb") as it handles character encoding internally.
The implication of using ijson is that developers can now tackle previously unmanageable datasets within Python, opening doors for more complex analyses and larger-scale data pipelines without resorting to external tools or specialized hardware solely for JSON parsing. This democratizes the processing of big data within the familiar Python ecosystem.
In conclusion, while Python’s standard json module is excellent for everyday JSON handling, the ijson library provides a vital solution for processing large JSON files efficiently. By embracing iterative parsing, developers can overcome memory limitations, enhance application performance, and unlock the potential of even the most substantial JSON datasets. The core principle remains: if your task requires data one record at a time, there is no inherent need to load every record simultaneously.